
Let’s explore the Red Hat OpenShift AI dashboard and create a dataset. Then we’ll create a workbench for your notebook.
Prerequisites:
- Access to the Developer Sandbox (OpenShift AI is a core component of the Developer Sandbox).
- A GitHub account.
In this learning path, you will:
- Explore an OpenShift AI dashboard AI project.
- Create a data science project.
- Create a workbench.
- Execute a Jupyter notebook.
Explore the OpenShift AI dashboard
To begin, let’s initiate an OpenShift AI instance from a Developer Sandbox cluster. Initiating this instance will enable you to explore the myriad of possibilities offered by artificial intelligence and machine learning (AI/ML).
The following steps will get you started with OpenShift AI:
- Log in to your Developer Sandbox cluster to access the Hybrid Cloud Console dashboard.
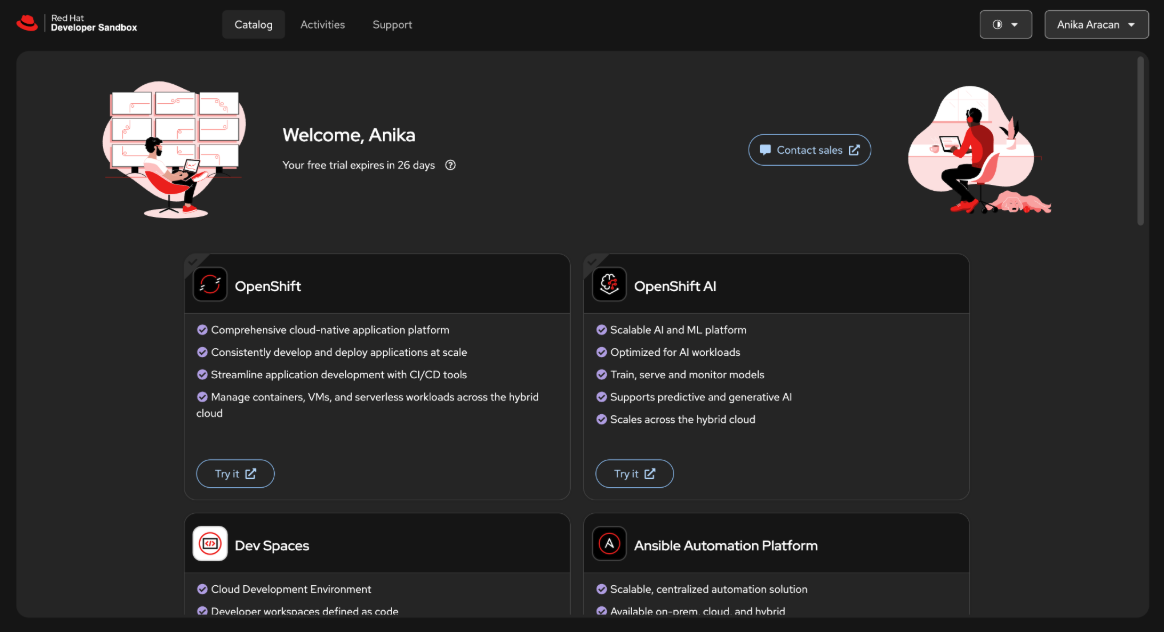
You will see the dashboard (Figure 1). Click Try it inside the Red Hat OpenShift AI tile.
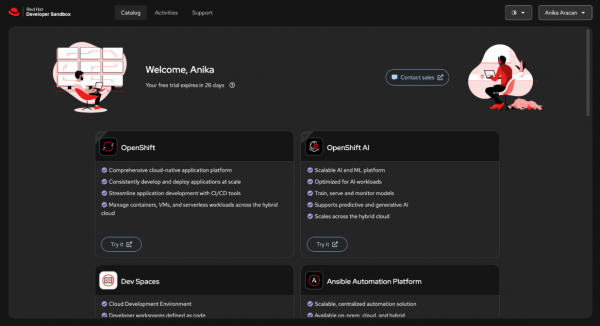
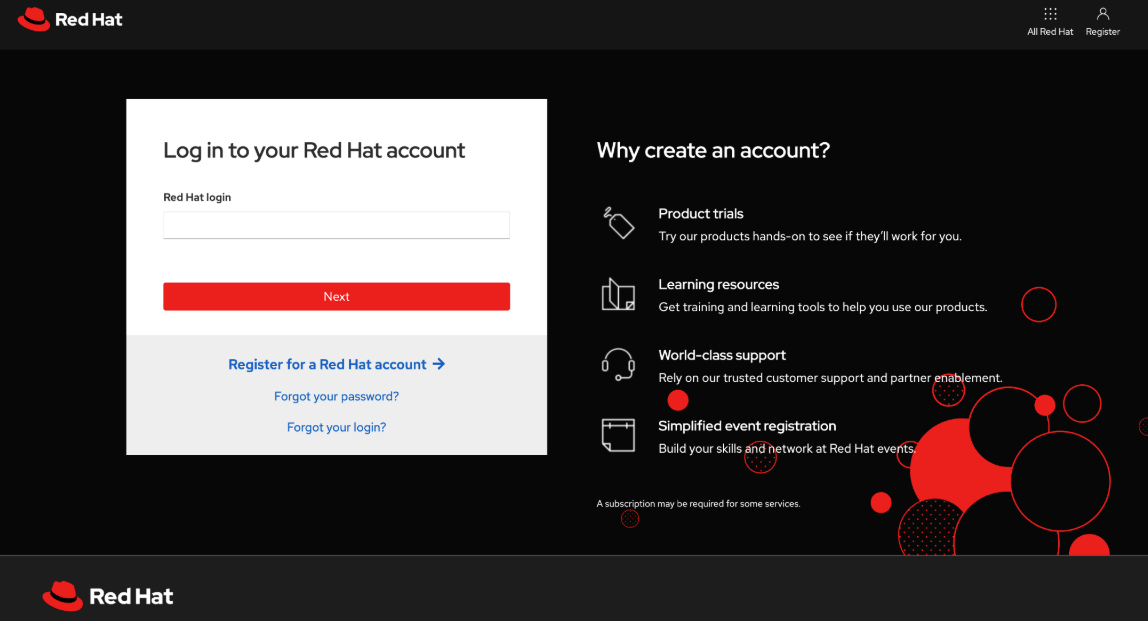
Figure 1: Access the Hybrid Cloud Console dashboard to launch OpenShift AI. Sign in with your Red Hat account for the Developer Sandbox. (Figure 2).
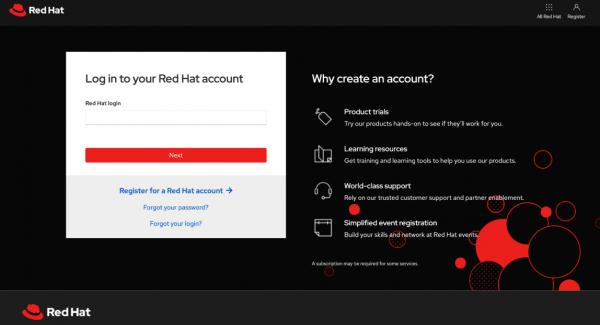
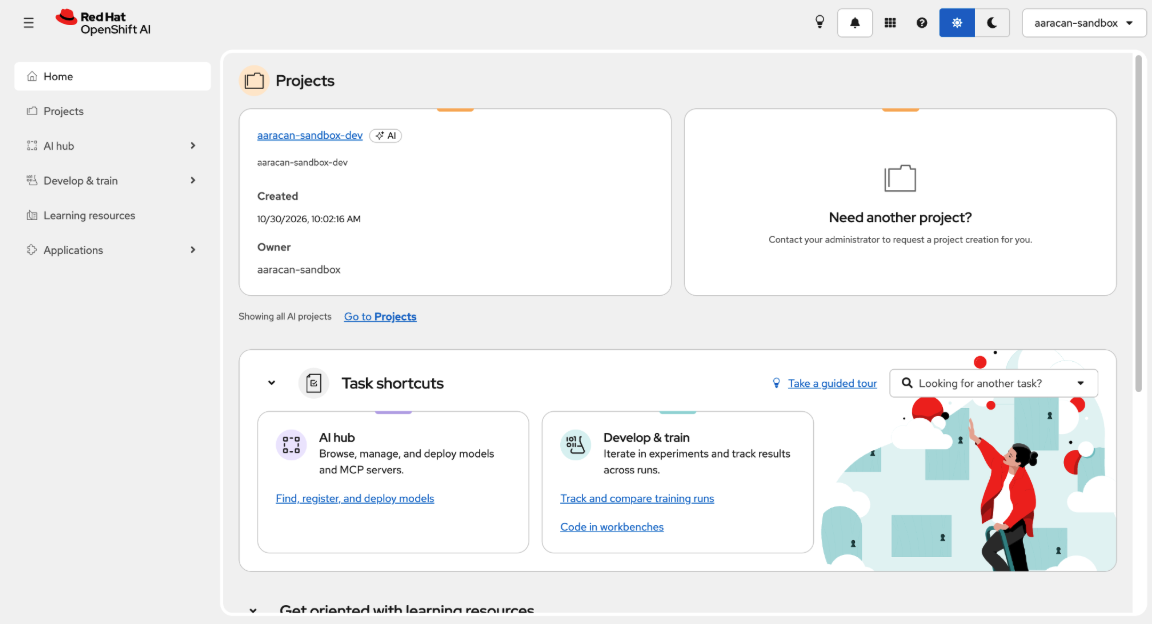
Figure 2: Login page. You will be taken to the OpenShift dashboard, where you will see the heading for Projects (Figure 3).
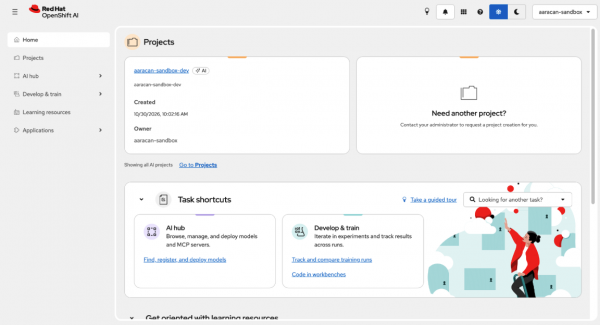
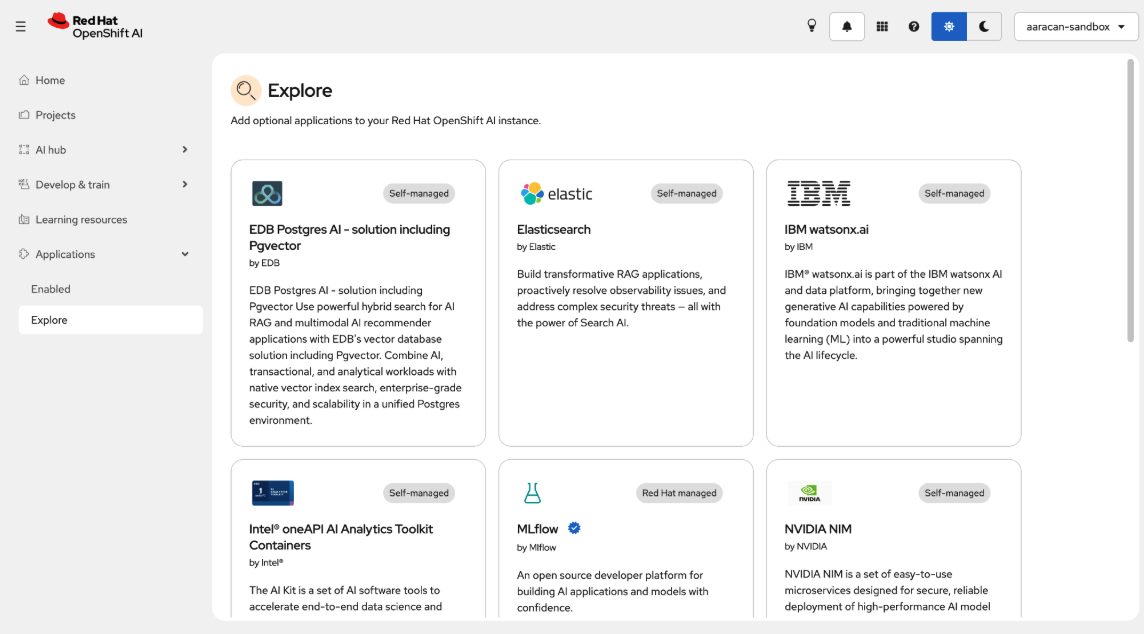
Figure 3: Red Hat OpenShift offers a multitude of instances. Also on the OpenShift AI dashboard, you can use the Explore option under Applications to view additional options for applications of Red Hat OpenShift AI instances (Figure 4).
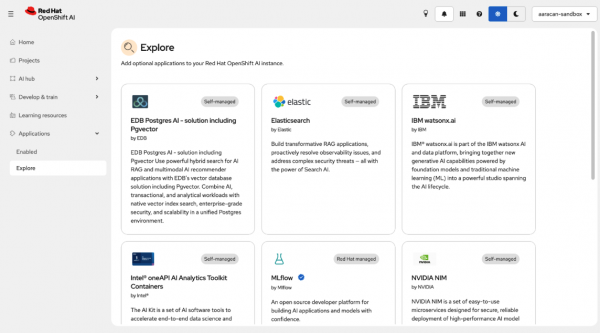
Figure 4: Red Hat OpenShift offers a multitude of instances.
To learn more, the Learning resources tab provides tutorials and documentation on how to use OpenShift AI, including partner software. Quickstarts are embedded in the application and offer an in-line tutorial experience.
Create a data science project
In this learning path, we will configure a Jupyter notebook server using a specified image within a project and customize it to meet your specific requirements. In the Developer Sandbox environment, a project is created for your convenience. Navigate to and open this project to set up a workbench, then follow these steps:
Click the Projects tab. You should see the created data science project with your username (Figure 5). Click it to open the project.
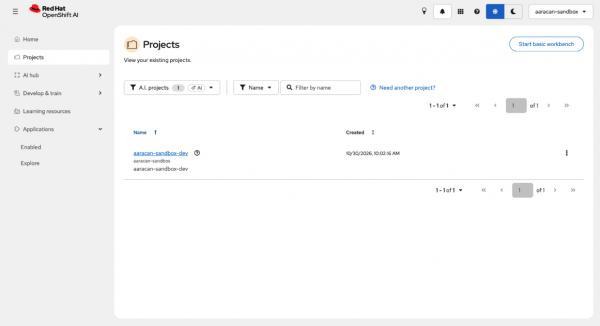
Figure 5: You can create a project in the Projects page. - Once you click the project with your username, a screen will appear with more details of your project, along with a link to create a workbench.
Click Create a workbench (Figure 6).
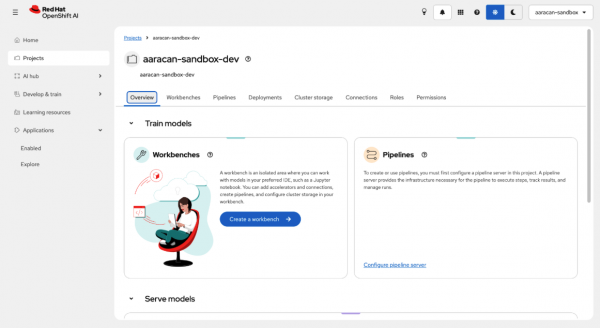
Figure 6: Your project has a link to create a workbench.
Establish a workbench for your Jupyter notebook server
Now you are ready to move to the next step to define the workbench.
After clicking Create a workbench, you’ll see a Create workbench configuration window where you can create a Jupyter network.
The data science project serves as a registry for the Jupyter notebook we will create. You will be directed to the component page of the data science project. In this configuration window, we need to define the configurations of Jupyter notebook server images, such as Data Science, TensorFlow, PyTorch, and others (Figure 7).
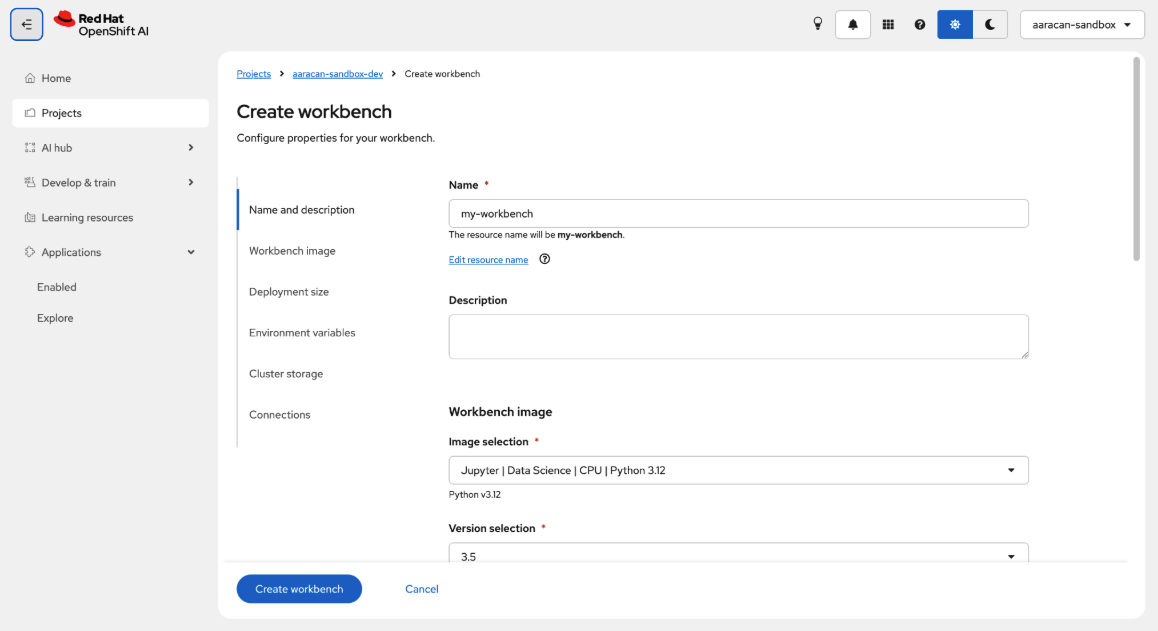
On the Create workbench page, fill in the following workbench parameters:
- Give the workbench a name.
- Select Jupyter | Data Science | CPU | Python 3.12 as the Notebook image from the image selection dropdown.
- Scroll down and give the storage cluster a storage name. The storage will default to a 20GB persistent volume. Leave this as is.
- Click the Create workbench button at the bottom of the page.
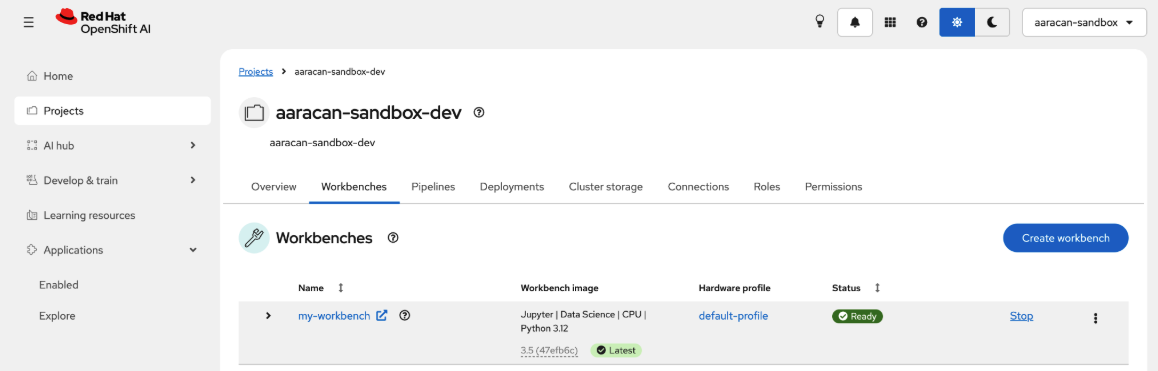
After successful implementation, the status of the workbench turns to Running (Figure 8).
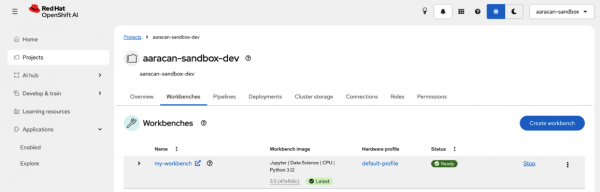
Figure 9: The workbench is in the running state. Figure 8: The workbench is in the running state. - Click the name of the workbench to open it.
You will be directed to the Jupyter Notebook page (Figure 9).
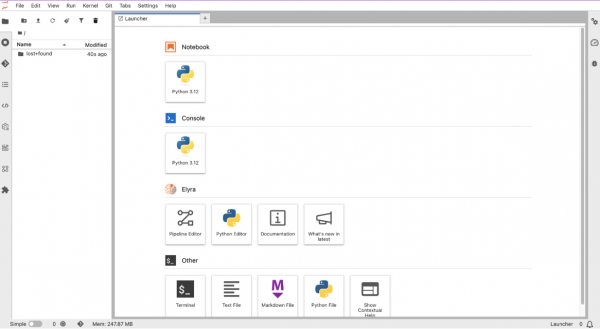
Figure 9: The Jupyter Notebook landing page.
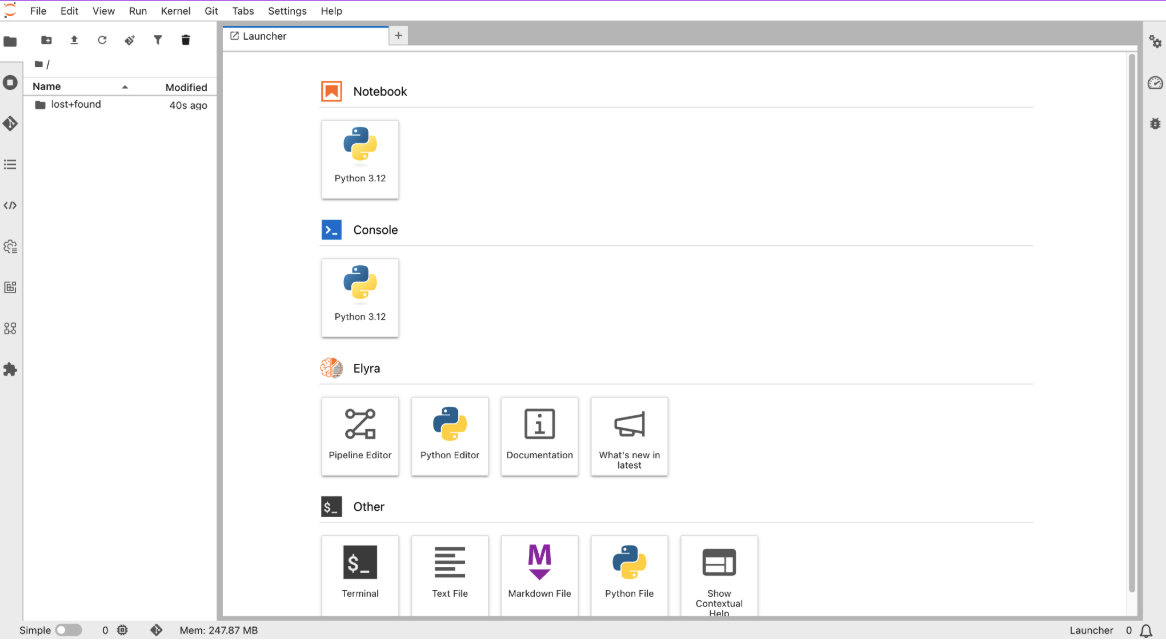
How to access the current data science project within Jupyter notebook
The Jupyter notebook provides functionality to fetch or clone existing GitHub repositories, similar to any other standard IDE. Therefore, we will clone an existing simple AI/ML code into the notebook using the following instructions:
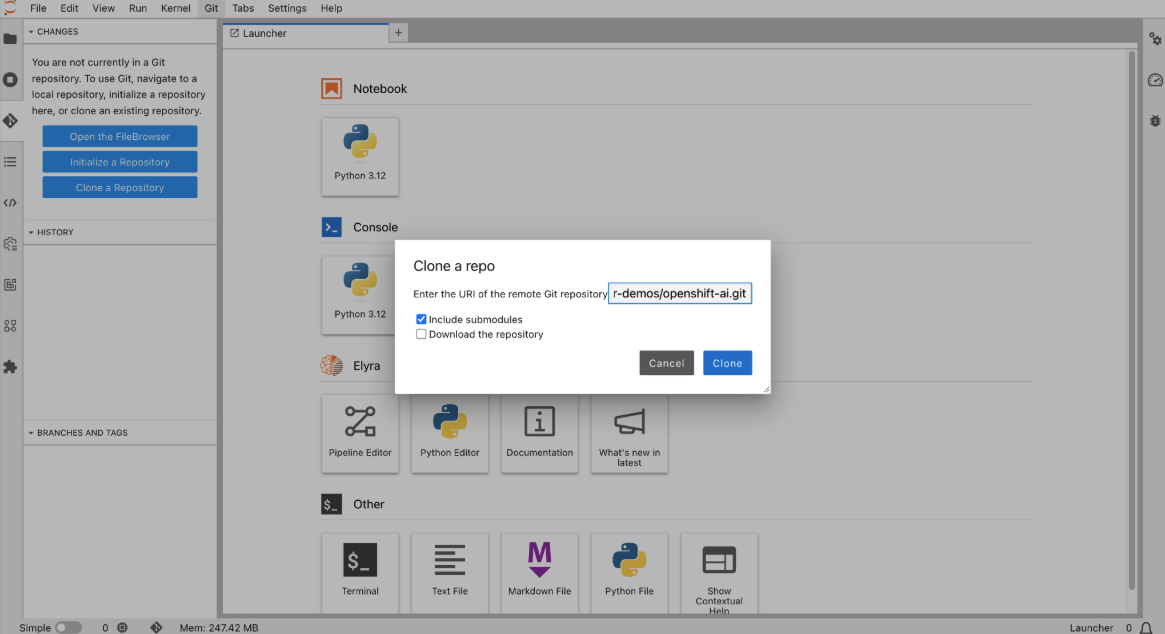
- Click on the Git menu, and choose Clone a Repository.
- In the pop-up window, define the following GitHub URL: https://github.com/redhat-developer-demos/openshift-ai.git
Click the Clone button (Figure 10).
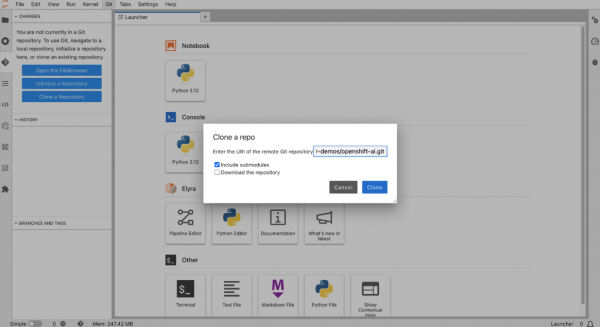
Figure 10: Click the Clone button in the GitHub URI.
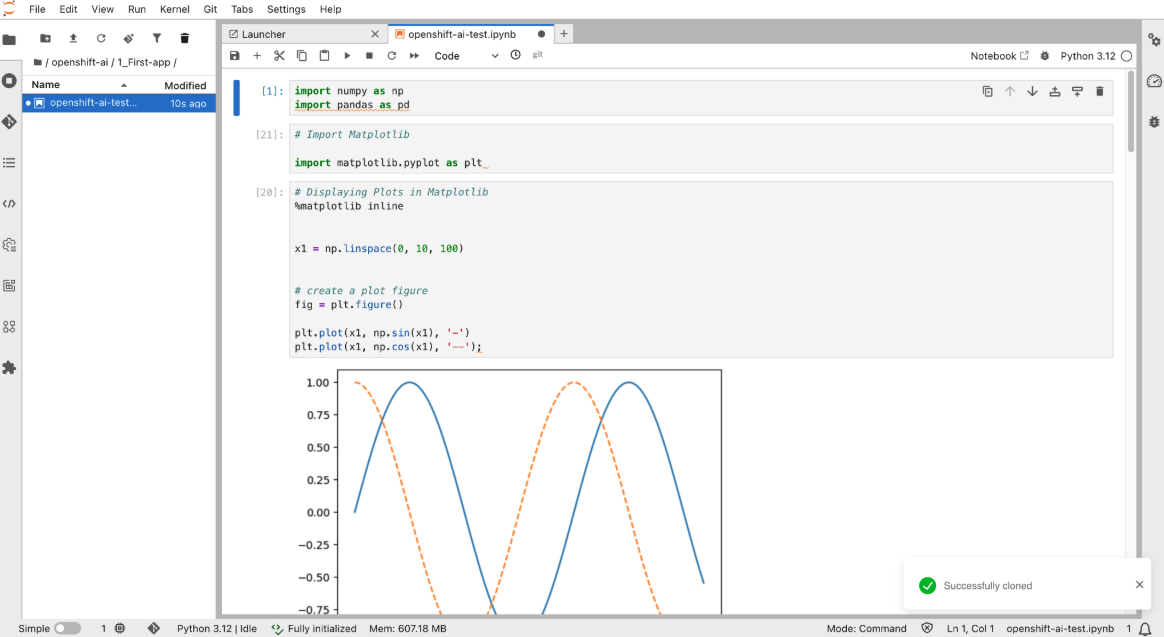
After fetching the GitHub repository, the project will appear in the directory section on the left side of the notebook:
- Navigate to the
/openshift-ai/first-app/directory. - Click the
openshift-ai-test.ipynbfile.
You will be presented with the view of a Jupyter notebook.
Learn how to execute code in a Jupyter notebook
Earlier, we imported and opened the notebook. To run the code within the notebook, start by clicking the Run icon located at the top of the interface. This action initiates the execution of the code in the currently selected cell.
After you click Run, you will notice that the notebook automatically moves to the next cell. This is part of the design of Jupyter notebooks, where scripts or code snippets are divided into multiple cells. Each cell can run independently, allowing you to test specific sections of code in isolation. This structure greatly aids in both developing complex code incrementally and debugging it more effectively, as you can pinpoint errors and test solutions cell by cell.
For instance, after executing a cell, you can immediately see the output below it. This immediate feedback loop is invaluable for iterative testing and refining of code (Figure 11).
Summary
This learning path guided you through accessing OpenShift AI from the Developer Sandbox cluster and demonstrated the process of fetching a GitHub repository within the JupyterLab environment. Additionally, we explored utilizing the Jupyter IDE and executing sample machine learning programs.
Our aim is to ensure the success of your data science projects, not merely as experiments, but as integral components of the next generation of intelligent applications.

