AI
  • Get started with AI

    • Red Hat AI

      Accelerate the development and deployment of enterprise AI solutions.

    • AI learning hub

      Explore learning materials and tools, organized by task.

    • AI interactive demos

      Click through scenarios with Red Hat AI, including training LLMs and more.

    • AI/ML learning paths

      Expand your Red Hat OpenShift AI knowledge using these learning resources.

    • AI quickstarts

      Focused AI use cases designed for fast deployment on Red Hat AI platforms.

    • No-cost AI training

      Foundational Red Hat AI training.

  • Featured resources

    • Red Hat OpenShift AI
    • Open source AI for developers
    • AI product application development
    • Open source-powered AI/ML for hybrid cloud
    • AI and Node.js cheat sheet

Red Hat AI Factory with NVIDIA

Red Hat AI Factory with NVIDIA is a co-engineered, enterprise-grade AI solution for building, deploying, and managing AI at scale across hybrid cloud environments.

Learn
  • Self-guided

    • Documentation

      Find answers, get step-by-step guidance, and learn how to use Red Hat products.

    • Learning paths

      Explore curated walkthroughs for common development tasks.

    • Guided learning

      Receive custom learning paths powered by our AI assistant.

    • See all learning
  • Hands-on

    • Developer Sandbox

      Spin up Red Hat's products and technologies without setup or configuration.

    • Interactive labs

      Learn by doing in these hands-on, browser-based experiences.

    • Interactive demos

      Click through product features in these guided tours.

  • Browse by topic

    • AI/ML
    • Automation
    • Java
    • Kubernetes
    • Linux
    • See all topics
  • Training & certifications

    • Courses and exams
    • Certifications
    • Skills assessments
    • Red Hat Academy
    • Learning subscription
    • Explore training
Build
  • Get started

    • Red Hat build of Podman Desktop

      A downloadable, local development hub to experiment with our products and builds.

    • Developer Sandbox

      Spin up Red Hat's products and technologies without setup or configuration.

  • Download products

    • Red Hat Enterprise Linux
    • Red Hat AI
    • Red Hat OpenShift
    • Red Hat Ansible Automation Platform
    • See all products
  • Featured

    • Red Hat build of OpenJDK
    • Red Hat JBoss Enterprise Application Platform
    • Red Hat OpenShift Dev Spaces
    • Red Hat Developer Toolset
  • References

    • E-books
    • Documentation
    • Cheat sheets
    • Architecture center
Community
  • Get involved

    • Events
    • Live AI events
    • Red Hat Summit
    • Red Hat Accelerators
    • Community discussions
  • Follow along

    • Articles & blogs
    • Developer newsletter
    • Videos
    • Github
  • Get help

    • Customer service
    • Customer support
    • Regional contacts
    • Find a partner

Join the Red Hat Developer program

Download Red Hat products and project builds, access support documentation, learning content, and more.

ConsoleDocsSupport Search
New For you

Recommended

We'll recommend resources you may like as you browse. Try these suggestions for now.

  • Product downloads
  • Cheat sheets
  • Red Hat Developer learning portal
  • Developer blog
  • E-books
  • Developer Sandbox
Log in

Get more with a Red Hat Developer account

  • Product downloads
  • Console access
  • Event registration
  • Training & trials
Explore more account benefitsLog in or register

A subscription may be required for some services.

Contact us

Fine-tune AI pipelines in Red Hat OpenShift AI 3.3

February 26, 2026
Ana Biazetti Brian Gallagher Michal Stokluska
Related topics:
Artificial intelligenceAutomationData science
Related products:
Red Hat AIRed Hat OpenShift AI

    Enterprises are moving from experimentation toward customized, production-grade models. Every organization has unique data requirements, compliance standards, and performance goals. The path from a base model to a fine-tuned asset should be a flexible, repeatable process rather than a rigid "black box."

    To support this need for flexibility, we introduced new example AI pipelines for fine tuning in Red Hat OpenShift AI 3.3. These AI pipelines offer a modular, automated framework for model fine-tuning. They use Kubeflow Trainer to distribute workloads and support both supervised fine-tuning (SFT) and orthogonal supervised fine-tuning (OSFT) techniques via Training Hub.

    The challenge: Moving beyond manual one-offs

    Direct model training or fine-tuning, often called the fast path, is excellent for quick iterations. However, it often lacks the governance and reproducibility required for enterprise production. Conversely, fixed, manual end-to-end scripts can quickly become stale and are difficult to extend as project needs change.

    Enterprises need a way to:

    • Maintain governance: Create reproducible workflows where every fine-tuned model can be traced back to its specific run, code, and dataset.
    • Achieve precision: Go beyond general knowledge to achieve high-performance, custom behavior tailored to specific business data.
    • Avoid "shadow AI": Provide AI engineers with a centralized, easy-to-use platform that mitigates the risk of teams adopting non-compliant external solutions.

    Composable AI pipelines and reusable components help you streamline OpenShift AI capabilities.

    AI pipelines allow users to build portable, scalable workflows using a Python-centric SDK. Complementing this, our new reusable components repository acts as a centralized hub for workflow building blocks. This repository helps you connect different OpenShift AI capabilities.

    Fine-tuning pipeline: Data preparation, fine-tuning, evaluation, and model registration

    The sample fine-tuning pipelines and associated reusable components provide a baseline workflow for model customization that includes the following steps, as illustrated in Figure 1.

    Flowchart showing a machine learning pipeline starting with dataset-download, followed by train-model and ending at kubefl...istry.
    Figure 1: Overview of fine-tuning pipeline.
    1. Download and validate the dataset: Download a dataset from Amazon S3, Hugging Face, or an HTTP URL. The component validates the dataset to ensure it’s in a suitable format for the fine-tuning algorithm. You can optionally split the dataset for training and evaluation. The component passes the dataset to the model training stage and optionally the evaluation stage.
    2. Train the model with Kubeflow Trainer: This component simplifies SFT and OSFT techniques. It downloads a base model and fine-tunes it based on your dataset and algorithm. You can download models from Amazon S3, Hugging Face, or an OCI registry, including the internal Openshift AI model catalog. The step outputs a fine-tuned model, training loss graph (see Figure 2), and training metrics.
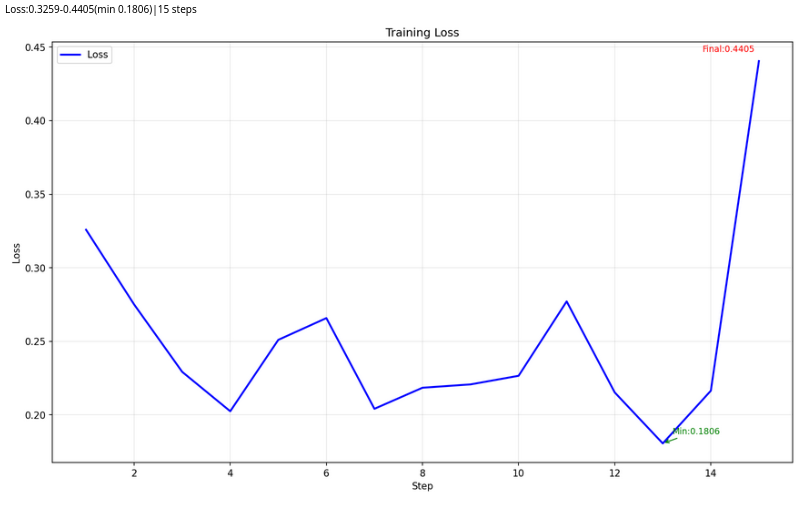
      Line graph showing training loss over 15 steps, starting at 0.3259, reaching a minimum of 0.1806, and finishing at 0.4405.
      Figure 2: Training loss chart generated by the training step.
    3. Evaluate the model: The LM-eval component runs benchmark tasks and ensures the new model meets performance requirements (Figure 3). You can select from a list of benchmark tasks and use the split dataset from step one for deeper evaluation.
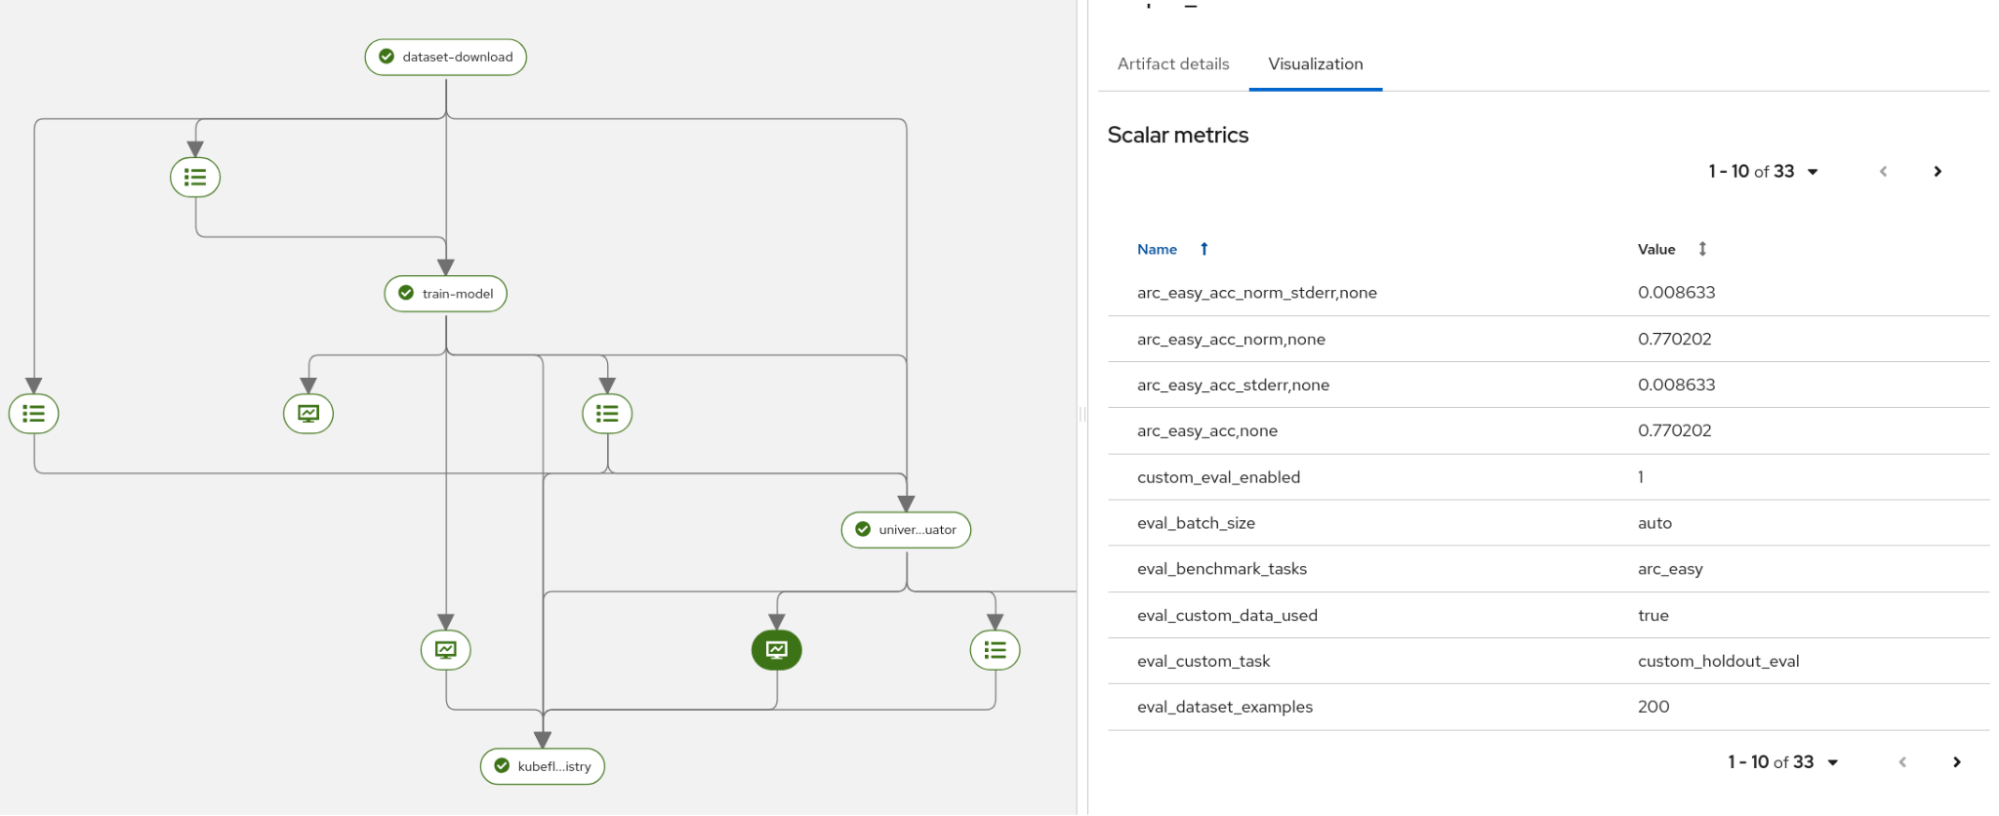
      Dashboard showing a completed evaluation pipeline alongside a table of scalar metrics including accuracy and error values.
      Figure 3: Part of evaluation generated metrics.
    4. Register the model: The fine-tuned model and its metrics are registered in the OpenShift AI model registry (Figure 4). This centralizes model lineage and artifacts. From here, you can serve the model for inference.
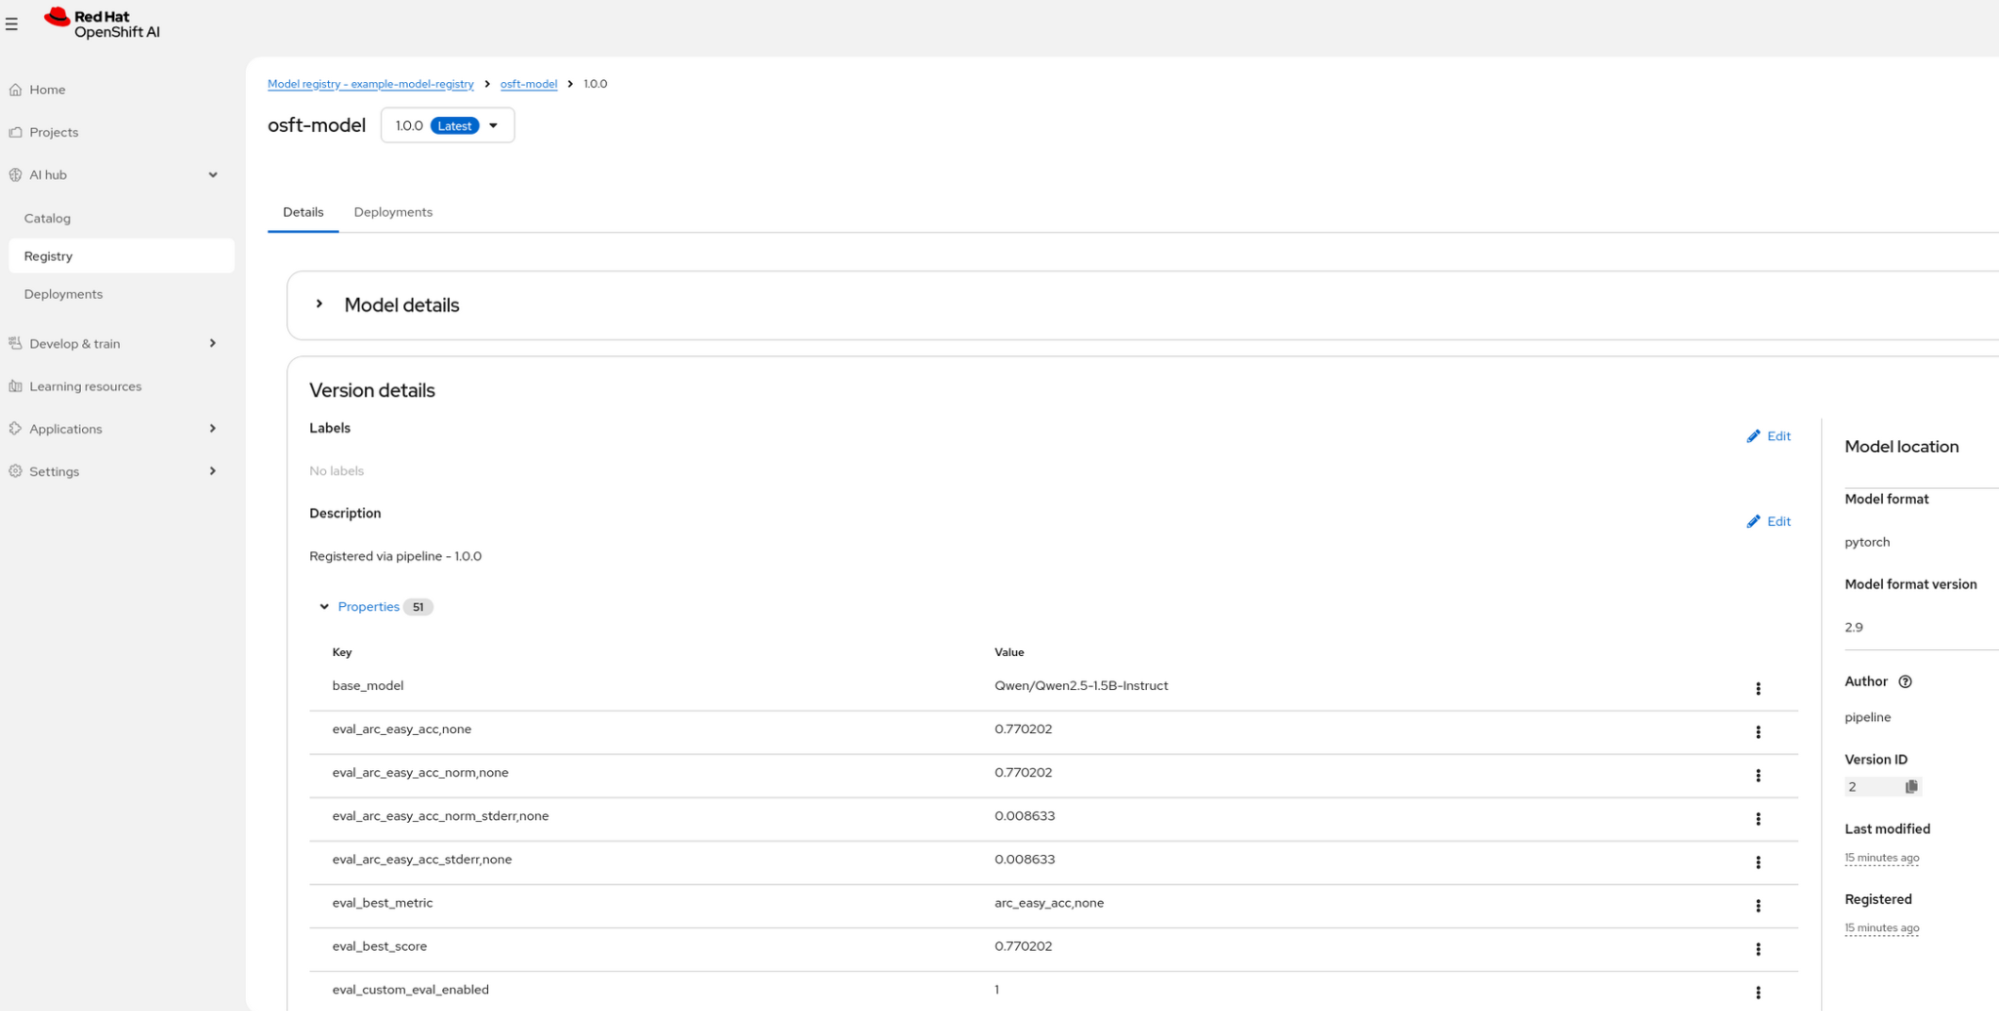
      Red Hat OpenShift AI model registry page showing version details and scalar evaluation metrics for the registered model osft-model.
      Figure 4: Model registry with saved model.

    Together, these four steps create a complete, auditable pipeline from raw data to a production-ready model.

    Choosing the right path: Our new pipeline options

    To support both rapid experimentation and deep customization, we are providing four distinct pipeline versions. These allow you to choose between a "ready-to-go" experience and a fully configurable environment.

    • The minimal pipelines (sft_minimal_pipeline and osft_minimal_pipeline): Designed for initial trials, these versions include multiple defaults and only expose the most critical top-level input parameters. They are perfect for users who want to see results quickly without navigating complex configurations.
    • The full pipelines (sft_pipeline and osft_pipeline): These provide granular control over every aspect of the fine-tuning process, from specific hardware resource mapping to detailed algorithm presets.

    Customize the pipelines for your environment

    The new sample fine-tuning AI pipelines serve as a validated pattern focused on core model customization, fine-tuning, and governance steps. Designed for flexibility, these validated patterns can be cloned and modified to suit your specific architectural needs.

    To start using the fine-tuning AI pipelines, visit the guided example. It walks you through OSFT-based fine-tuning using the reusable pipelines.

    The guided example also provides information on:

    • Reusing components in your own pipelines.
    • Customizing the existing pipelines.
    • Adding and removing parameters.
    • Running the pipeline on the OpenShift AI platform.

    To build your own pipeline using a combination of the dataset, fine-tune, eval, or register components or any other custom component:

    1. Clone the pipelines-components repository.
    2. Import the components you need.
    3. Compose them into your custom pipeline.
    4. Add any additional custom steps (e.g., data preprocessing, model conversion, deployment).

    Why this approach matters: Your pipeline, your way

    Shifting from fixed solutions to modular building blocks in Red Hat OpenShift AI 3.3 helps you customize workflows at scale. Modular components ensure the pipeline is not a fixed solution. You can share and adapt them across different teams and use cases. The example fine-tuning pipelines provide a baseline for automating model customization in your AI scenarios.

    As you explore these new capabilities in OpenShift AI 3.3, remember that these are your building blocks—designed to be adapted into the specific workflows that drive your business forward

    Related Posts

    • Fine-tune a RAG model with Feast and Kubeflow Trainer

    • Fine-tune LLMs with Kubeflow Trainer on OpenShift AI

    • How to fine-tune Llama 3.1 with Ray on OpenShift AI

    • Introduction to supervised fine-tuning dataset formats

    • From tuning to serving: How open source powers the LLM life cycle

    • How AMD GPUs accelerate model training and tuning with OpenShift AI

    Recent Posts

    • A day in the life of an NVIDIA H100 on Red Hat OpenShift 5

    • Migrate BuildConfigs to builds for Red Hat OpenShift with one plug-in install

    • Run Red Hat Enterprise Linux CoreOS on NVIDIA BlueField DPUs

    • Agent harness engineering: Separating model capabilities from enforcement

    • What's new for developers in Red Hat Enterprise Linux 10.3 and 9.9

    What’s up next?

    Learning Path intro-to-OS-LP-feature-image

    Introduction to Red Hat OpenShift AI

    Learn how to use Red Hat OpenShift AI to quickly develop, train, and deploy...
    Red Hat Developers logo

    Platforms

    • Red Hat AI
    • Red Hat Enterprise Linux
    • Red Hat OpenShift
    • Red Hat Ansible Automation Platform
    • See all products

    Build

    • Developer Sandbox
    • Developer tools
    • Interactive tutorials
    • API catalog

    Quicklinks

    • Learning resources
    • E-books
    • Cheat sheets
    • Blog
    • Events
    • Newsletter

    Communicate

    • About us
    • Contact sales
    • Find a partner
    • Report a website issue
    • Site status dashboard
    • Report a security problem

    Red Hat Developer

    Build here. Go anywhere.

    We serve the builders. The problem solvers who create careers with code.

    Join us if you’re a developer, software engineer, web designer, front-end designer, UX designer, computer scientist, architect, tester, product manager, project manager or team lead.

    Sign me up

    Red Hat legal and privacy links

    • About Red Hat
    • Jobs
    • Events
    • Locations
    • Contact Red Hat
    • Red Hat Blog
    • Inclusion at Red Hat
    • Cool Stuff Store
    • Red Hat Summit
    © 2026 Red Hat

    Red Hat legal and privacy links

    • Privacy statement
    • Terms of use
    • All policies and guidelines
    • Digital accessibility
    Ask AI